

Imagine This
You’re designing the next big e-commerce platform, and everything looks great! Until your database starts slowing down 🐌… Orders take too long to process, customers are complaining about delays, and your analytics dashboard crashes every time someone queries sales data from last year.
You realize that your data model might be the problem. But wait! What even is a data model? And why does choosing the wrong one feel like setting a time bomb in your system 💣?
Before going further, make sure you’re familiar with a few basics: CRUD, schemas, cardinality, normalization, OLTP vs OLAP, ACID vs BASE, and horizontal vs vertical scaling (there are plenty of resources on the blog/web!).
Understanding Data Models
First of all, what is a data model? A data model defines how data is structured, how records relate to each other, and which operations and constraints apply. In a relational model, you work with tables, keys, and joins. In a document model, you group related fields and nested objects into documents. These choices shape how you query and update your data.
The practical question is what your application needs to do: process frequent transactions, scan years of historical records, retrieve values by key, or traverse relationships. Each approach comes with trade-offs in flexibility, integrity, and performance.
There is no “one size fits all 👕” in this matter – Yassine
A data model is an abstraction, not a database product. PostgreSQL, Cassandra, MongoDB or Redshift are technologies that implement data models. Their engines handle storage, indexing, and query execution. A single technology can support several models. Even within the same model, engines can organize data differently on disk: relational tables can be stored row by row to access individual records, or column by column to scan selected fields across many records.
1️⃣ Relational Databases (RDBMS), or the structured workhorses
Relational databases have been the backbone of structured data storage since the early days of computing in the 1970s. Initially built for heavy business applications that demanded strong consistency, they remain widely used today, and have even evolved to incorporate some NoSQL-style features.
- Structure: Data is stored in structured tables with rows and columns.
- Schema enforcement: Schema-on-write, data must adhere to a predefined structure before insertion.
- Cardinality pattern: Supports all cardinality patterns. Other technologies can be more suitable for one-to-many (document-oriented) and many-to-many (graph-oriented) data.
- Read/Write behavior: Fully supports CRUD (Create, Read, Update, Delete) operations, with write patterns typically consisting of high-frequency and small-sized transactions.
- Consistency model: Fully ACID-compliant (Atomicity, Consistency, Isolation, Durability).
- Normalization: Typically highly normalized to reduce redundancy and ensure integrity.
- Historical data: Mainly optimized for storing the current state, allowing fast lookups and efficient index management. Historical data is typically offloaded to separate tables or analytical systems that use columnar storage for better performance.
- Scalability: Traditionally vertical scaling (adding more power to a single server); horizontal scaling is complex and requires sharding or replication strategies.
- Best suited for: OLTP systems like financial systems, ERP, inventory management, CRM or transactional applications.
- Modern evolution: Many RDBMS now support JSON storage, distributed architectures, and also graphs (e.g. SQL Graph)!
- Technologies: PostgreSQL, MySQL, Microsoft SQL Server, Oracle, SQLite, CockroachDB
2️⃣ Document Databases, or the flexible choices
Document databases emerged in the 2000s as part of the NoSQL (Not-only SQL) movement, offering a more flexible way to store semi-structured data and scale out more easily. These qualities have made them popular for modern web applications.
- Structure: Data is stored as JSON-like documents (often in BSON format).
- Schema enforcement: Schema-on-read, documents can have different structures without a predefined schema.
- Cardinality pattern: Optimized for one-to-many relationships (tree-like relationships).
- Read/Write behavior: Supports CRUD (Create, Read, Update, Delete) pattern like RDBMS.
- Consistency model: BASE (Basically Available, Soft state, Eventual consistency) with some support for ACID transactions within a single document. Not to use for finance or ERP systems, when strong ACID is needed!
- Normalization: Typically denormalized, related data is stored within documents rather than in separate tables.
- Historical data: Can store both current state and historical data, but typically focuses on the current state of the data.
- Scalability: Horizontally scalable, with built-in sharding for large distributed workloads.
- Best suited for: User profiles, catalogs, content management, logging, flexible data applications.
- Common pitfall: Schema flexibility can lead to inconsistencies over time, making queries unpredictable.
- Technologies: MongoDB, CouchDB, Amazon DocumentDB
3️⃣ Key-Value Stores, or the speed demons
One of the oldest data storage models, key-value databases have been adapted for modern high-performance applications. They are used particularly for caching and real-time processing.
- Structure: Simple key-value pairs with no predefined schema.
- Schema enforcement: No schema, data is stored exactly as provided.
- Cardinality pattern: Supports only one-to-one lookups (each key maps to a single value).
- Read/Write behavior: Full CRUD by key (create, read, update, delete), with sub-millisecond inserts and lookups.
- Consistency model: BASE (tunable consistency), some offer strong consistency via replication.
- Normalization: No normalization, each key is independent.
- Historical data: Typically does not track history, focuses on the latest state, like the position of a player in a video game or session information.
- Scalability: Highly scalable horizontally, often used in distributed architectures.
- Best suited for: Caching, session storage, leaderboards, real-time analytics.
- Technologies: Redis, Memcached, DynamoDB
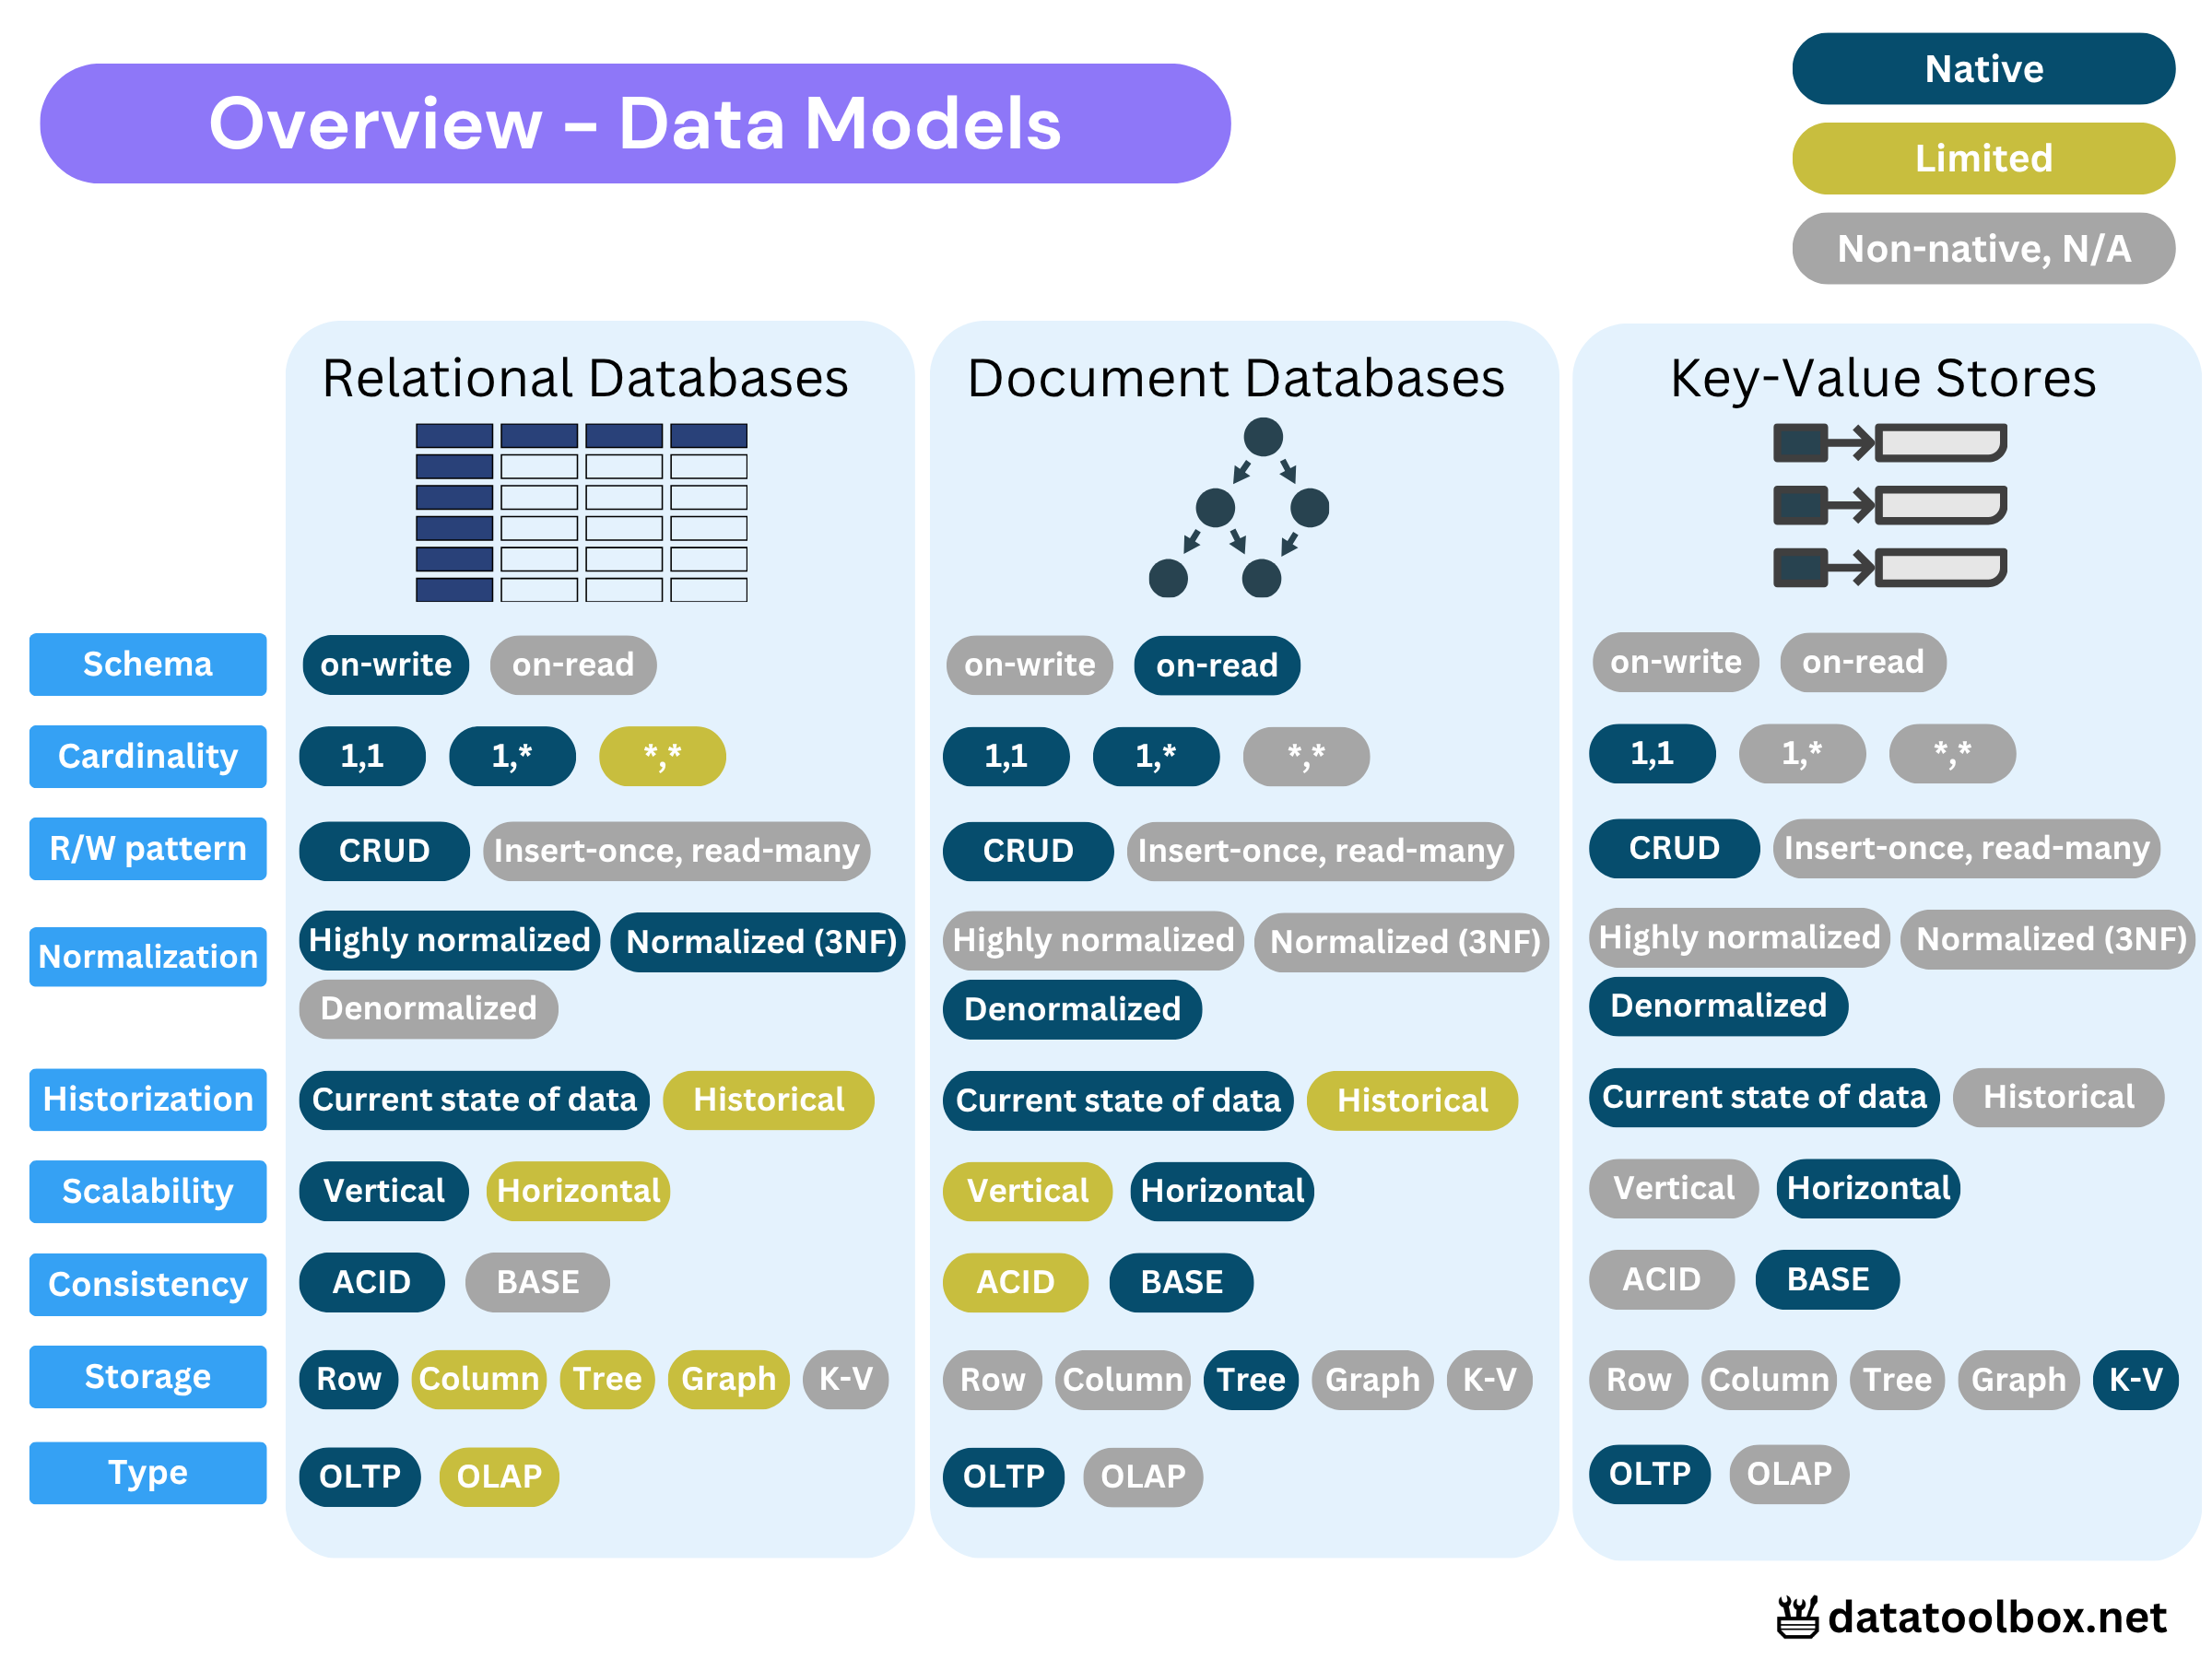
🤫 The one-pager recap you are waiting for:
4️⃣ Graph Databases, or the relationship powerhouses
Graph databases were developed in the 2000s to handle data where relationships are as important as the data itself, making them ideal for social networks and recommendation engines.
- Structure: Data is represented as nodes (entities) and edges (relationships).
- Schema enforcement: Schema can be optional for both relationships and nodes.
- Cardinality pattern: Optimized for many-to-many relationships.
- Read/Write behavior: Supports CRUD, but is specialized for graph traversal queries.
- Consistency model: ACID-compliant in most graph databases.
- Normalization: Some data can be denormalized within node properties, sometimes using JSON-like structures, to avoid unnecessary traversals.
- Historical data: Typically stores current state, but some support time-travel queries.
- Scalability: Difficult to scale horizontally, but distributed graph databases exist (e.g., JanusGraph).
- Best suited for: Social networks, fraud detection, recommendation engines, supply chain analysis.
- Examples: Neo4j, Amazon Neptune
5️⃣ Columnar Databases, or the analytical wizards
Here, we’re moving from logical data models to physical storage layouts. The RDBMS we discussed earlier typically stores data row by row, whereas a columnar database stores the values of each column together. This columnar layout changes the type of workload the database handles best. Instead of reading complete records, it can scan only the columns required by a query.
Columnar databases are therefore designed for heavy analytics, large-scale reporting and business intelligence, without putting pressure on transactional systems.
- Structure: Data is stored in structured tables with rows and columns, like in relational databases. However, under the hood, data is stored in a column format rather than by row (see heuristic here).
- Schema enforcement: Schema-on-write, with predefined columns.
- Cardinality pattern: Supports different relationship cardinalities and analytical joins.
- Read/Write behavior: Insert-once, read-many. Optimized for large batch queries.
- Consistency model: BASE (tunable consistency), optimized for large-scale reads.
- Normalization: Denormalized to optimize analytical queries.
- Historical data: Designed for storing and analyzing historical data.
- Scalability: Highly scalable, supports MPP (Massively Parallel Processing).
- Best suited for: Data warehousing/lakehousing, BI, ML, AI, operational analytics.
- Examples: BigQuery, Redshift, Snowflake, Teradata, ClickHouse
For info, Lakehouse platforms like Fabric and Databricks are considered as “columnar-ish.” While they don’t rely exclusively on columnar storage engines, they leverage columnar file formats such as Parquet, often through Delta Lake tables for efficient analytics. See Architectural Deep Dive: Data Lakehouse for more details.
6️⃣ Wide-Column Stores, or the scalable giants
Wide-column stores are built for high write throughput and massive distributed workloads. We saw that RDBMS are much harder to scale horizontally, especially when you want to keep strong ACID guarantees. If three database nodes must stay fully consistent, they need to coordinate writes and acknowledgements (which takes time, adds latency and creates more points of failure).
Wide-column stores relax some of these guarantees. If you don’t need strict consistency everywhere, writes can be distributed much more easily across many machines. In simple terms, it’s a bit like a horizontally scalable RDBMS with fewer guarantees to make scaling easier.
- Structure: Hybrid row-column model, each row can contain a flexible set of column key-value pairs tailored to its own schema.
- Schema enforcement: Schema-on-read, with rows that can vary in column structure.
- Read/Write behavior: Supports CRUD, optimized for high write throughput.
- Consistency model: BASE with tunable consistency settings.
- Normalization: Typically denormalized for fast lookups (most don’t support joins!).
- Historical data: Supports both current state and historical data tracking.
- Scalability: Horizontally scalable and built for distributed workloads.
- Best suited for: IoT, time-series, recommendation engines, clickstream data, event logging.
- Examples: Cassandra, Google Bigtable, Apache HBase, ScyllaDB
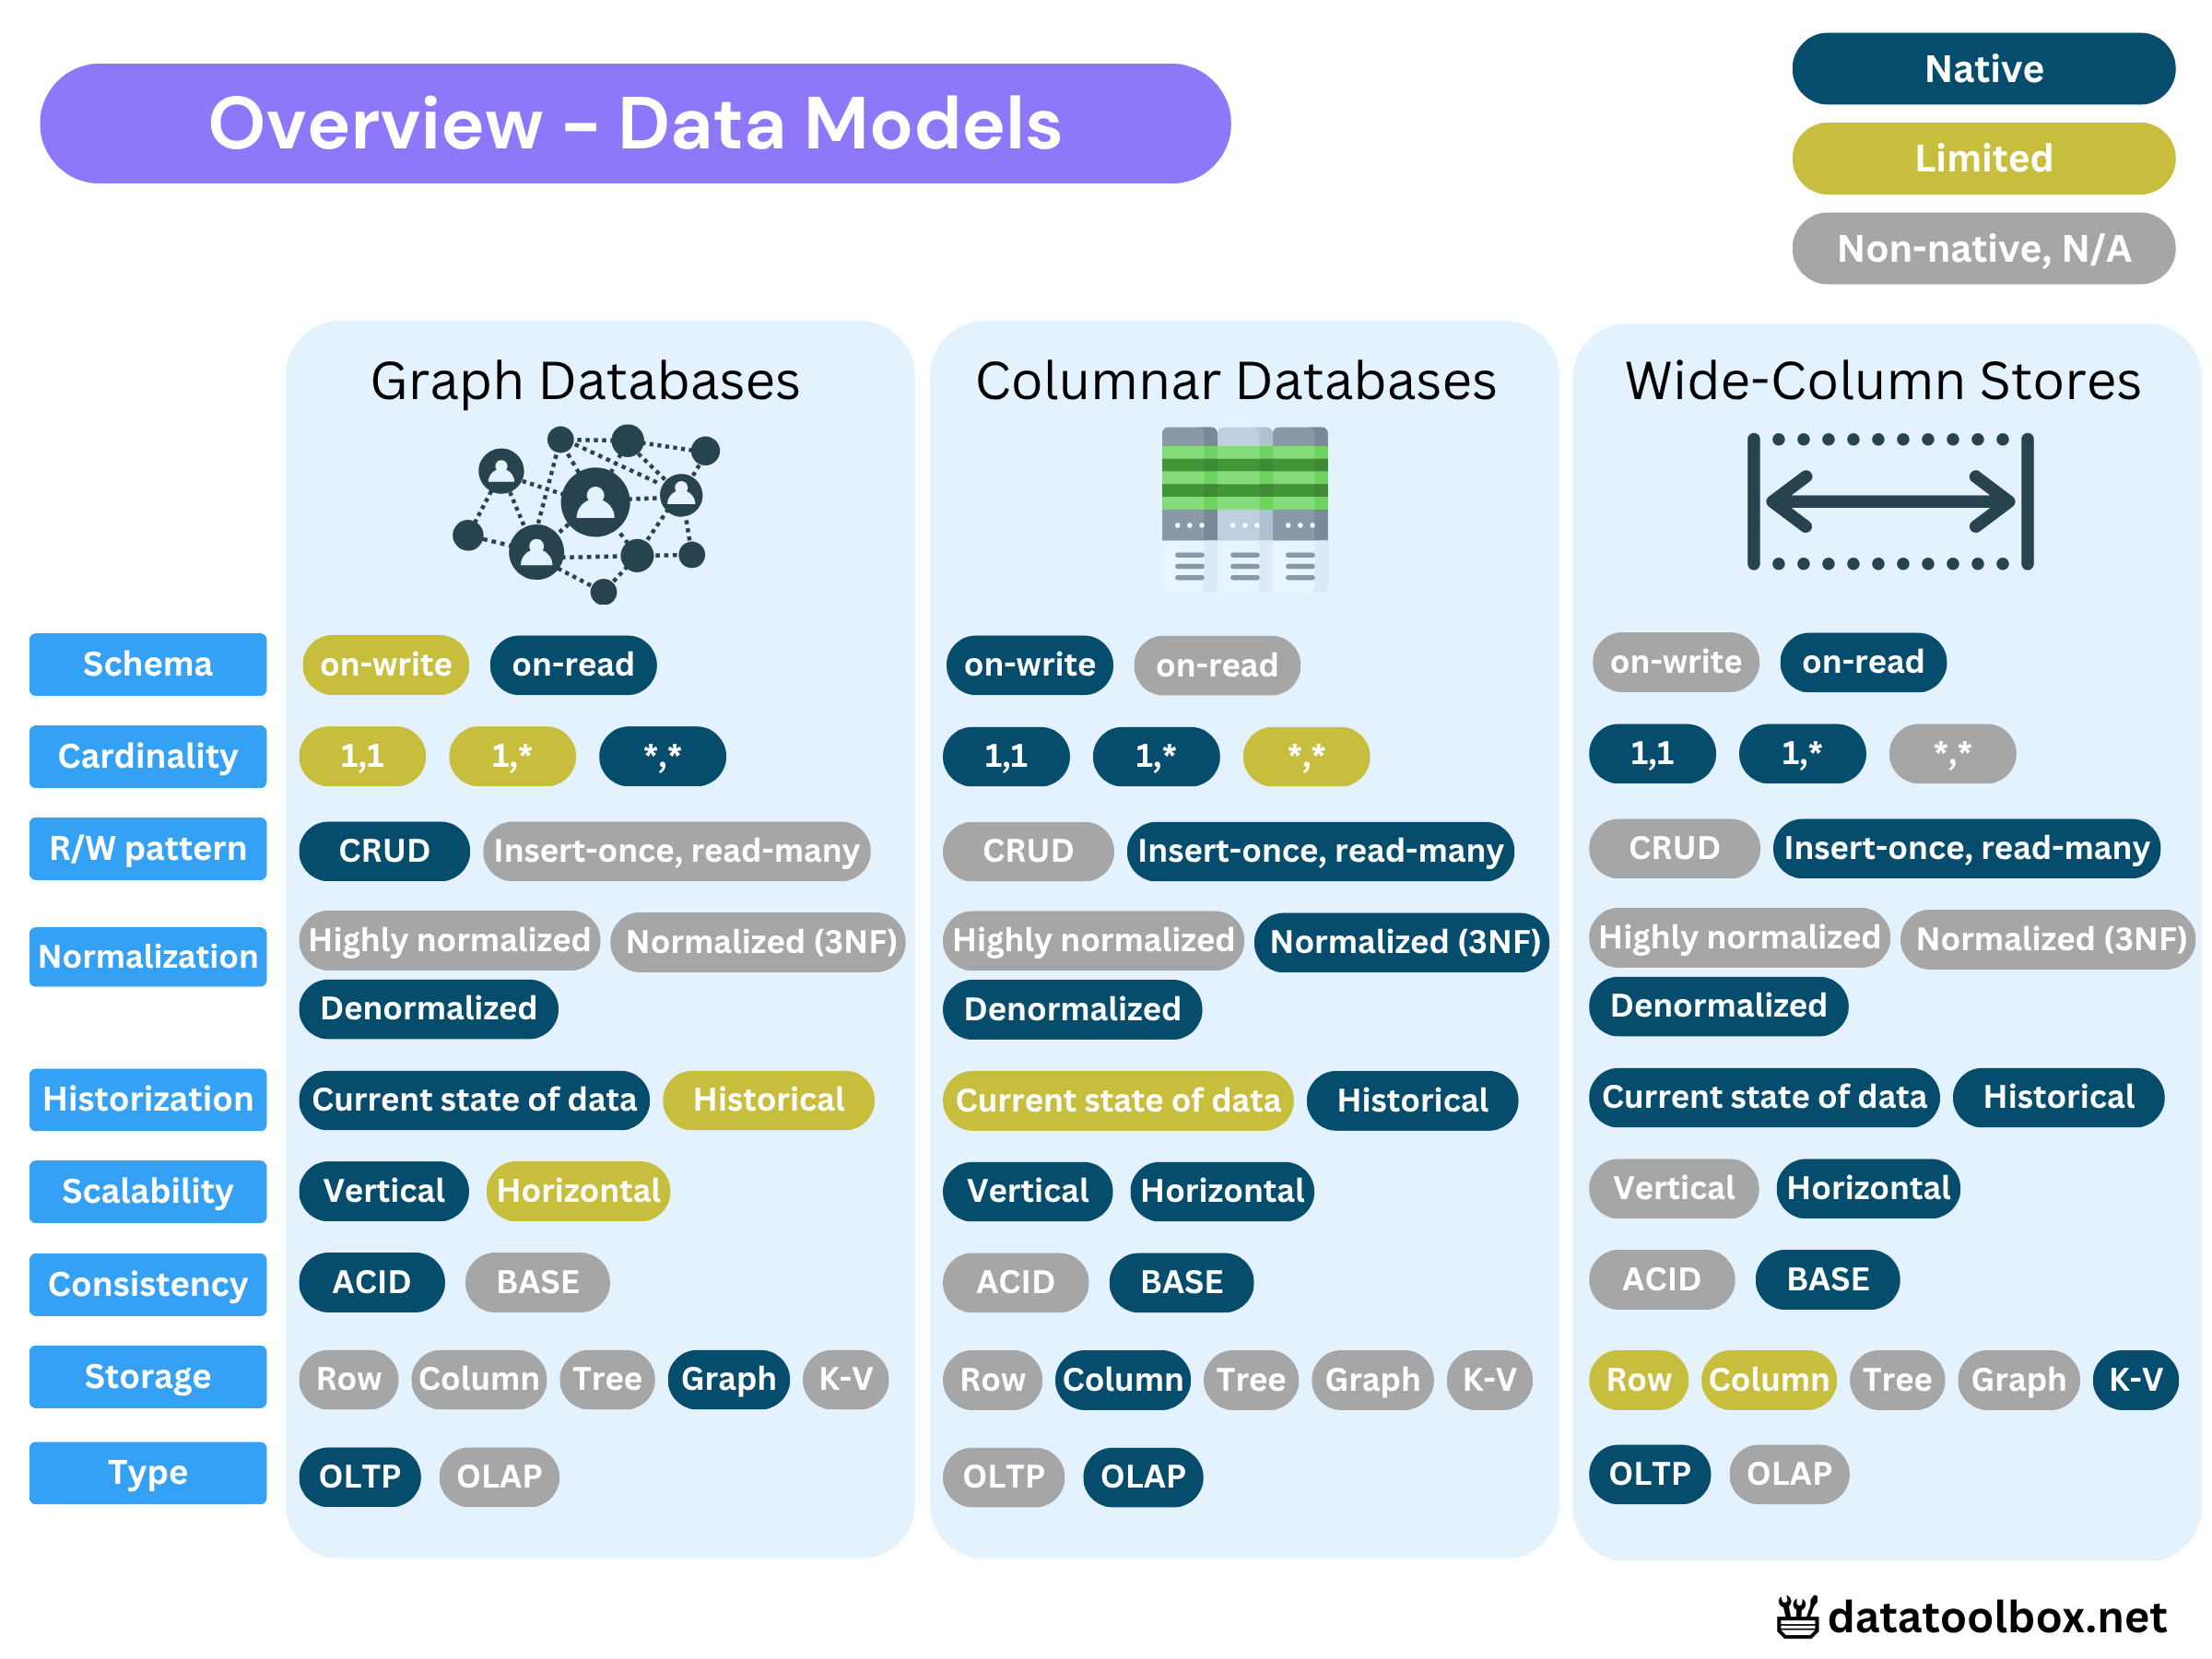
🤫 The one-pager recap you are waiting for:
Specialized Data Technologies
Some workloads need more than a general-purpose database. Searching by meaning, finding text in millions of documents, or analyzing measurements over time all require their own indexing and retrieval strategies. This is where specialized data technologies come in:
- Vector Databases and Tools (e.g. Pinecone, Weaviate, FAISS, pgvector) turn data into high-dimensional vectors and retrieve items based on similarity rather than exact matches. This is the foundation behind semantic search and many RAG systems.
- Search Engines (e.g. Elasticsearch, Apache Solr) are built to find and rank text quickly. Using inverted indexes and relevance scoring, they power use cases such as product search and log exploration.
- Time-Series Databases (e.g. InfluxDB, TimescaleDB) organize data around time. They are particularly useful when measurements arrive continuously and must be queried over specific periods, as with IoT sensors, system metrics, or market data.
Bridging Theory to Reality
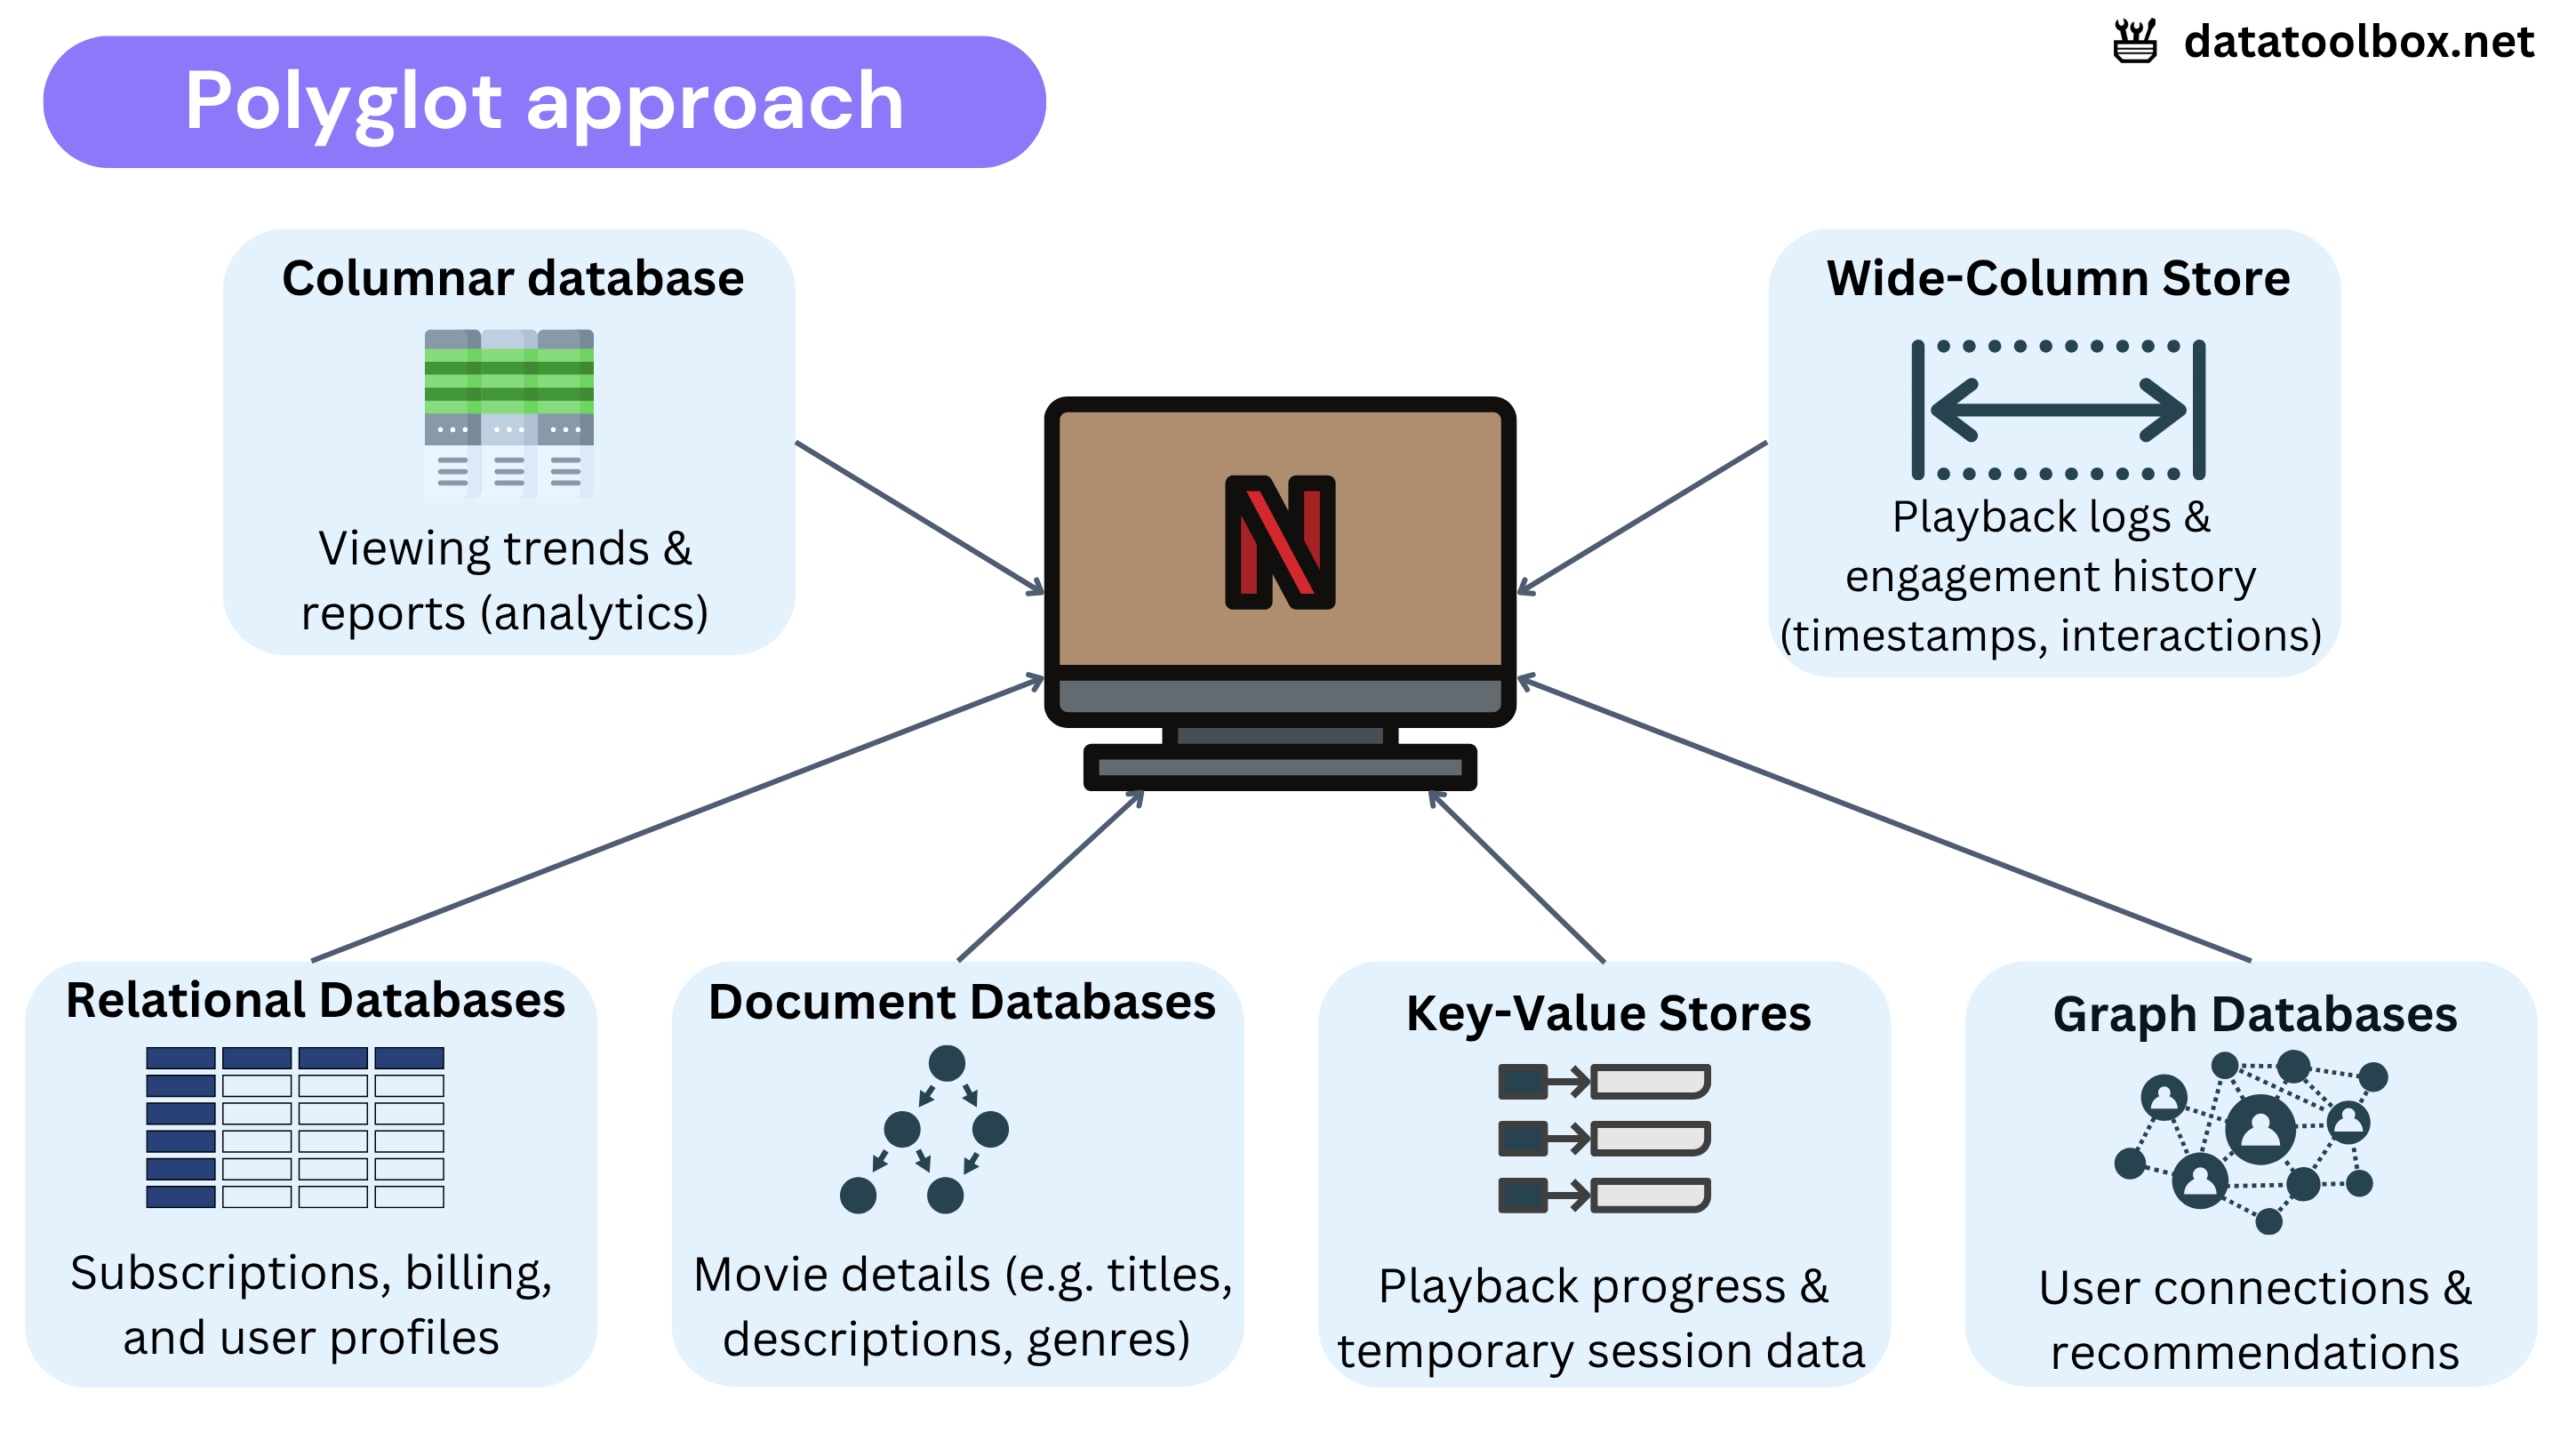
We call that a polyglot persistence approach. A single database type is rarely enough to meet all performance and scalability needs. Instead, we combine multiple databases, each optimized for a specific workload.
Key Takeaways
Don’t be Homer Simpson (Mmmh…)! Choosing the right data model is like picking the right tool for the job. You wouldn’t use a screwdriver to hammer a nail! Every database type has strengths and trade-offs, and modern systems mix and match to get the best of all worlds:
- 1️⃣ Pick the right tool: Databases are designed for specific workloads, so use them accordingly.
- 2️⃣ RDBMS still rules: The most widely used model! It’s now bridging gaps with NoSQL through JSON support.
- 3️⃣ NoSQL isn’t one thing: Document, key-value, graph, wide-column databases serve vastly different purposes.
- 4️⃣ Scalability matters: RDBMS typically scale vertically, with some supporting horizontal scaling, with a lot a lot of effort. In contrast, NoSQL databases are designed for horizontal scalability, though often at the cost of consistency.
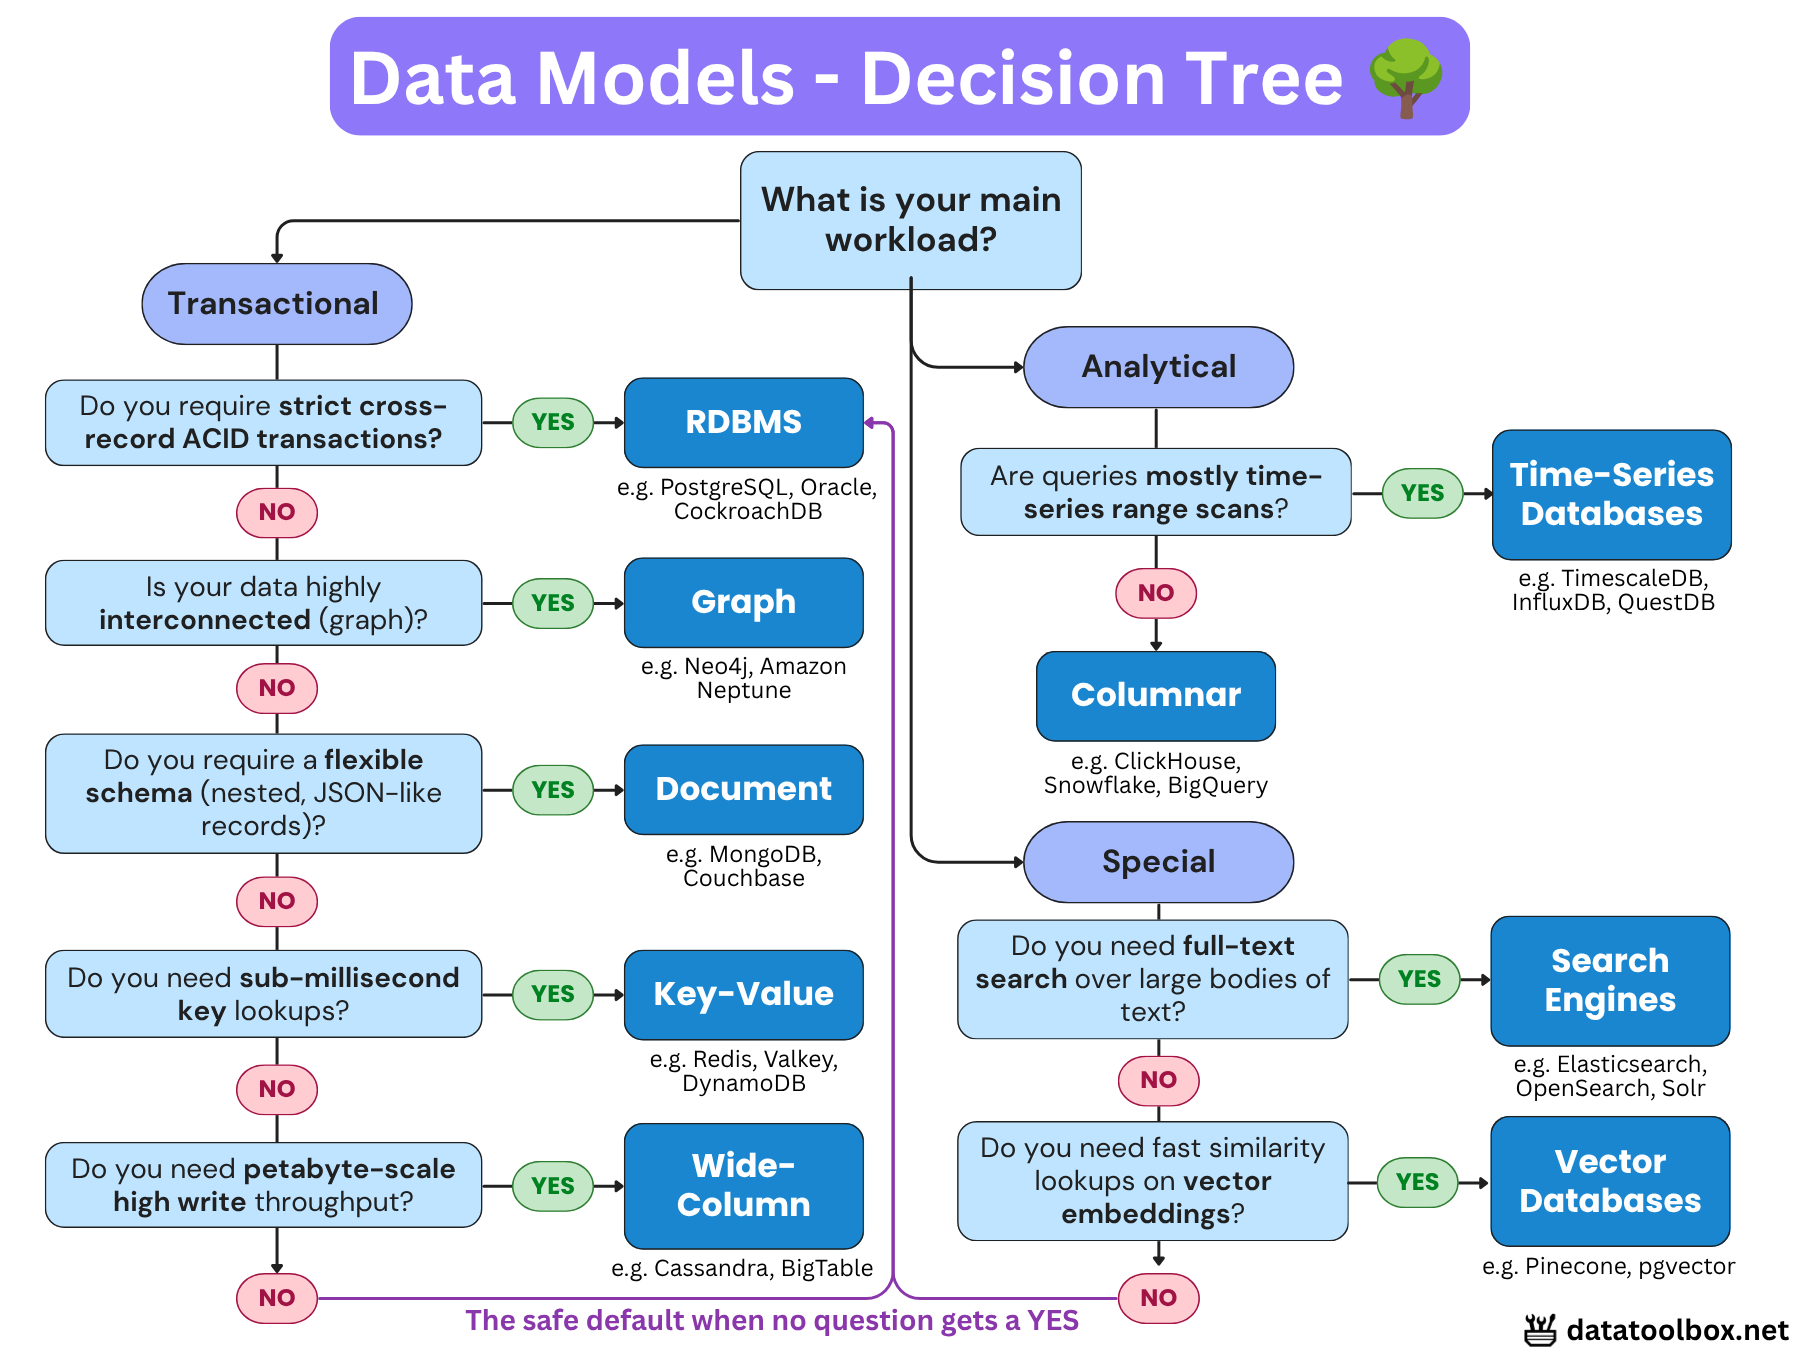
To recap, I have made for you a beautiful decision tree 🌳 so you quickly have a clue about what to choose and why:
👉 If you wish to expand your knowledge of database technologies, you can explore The Foundation of a Scalable Data Architecture: Data Storage.